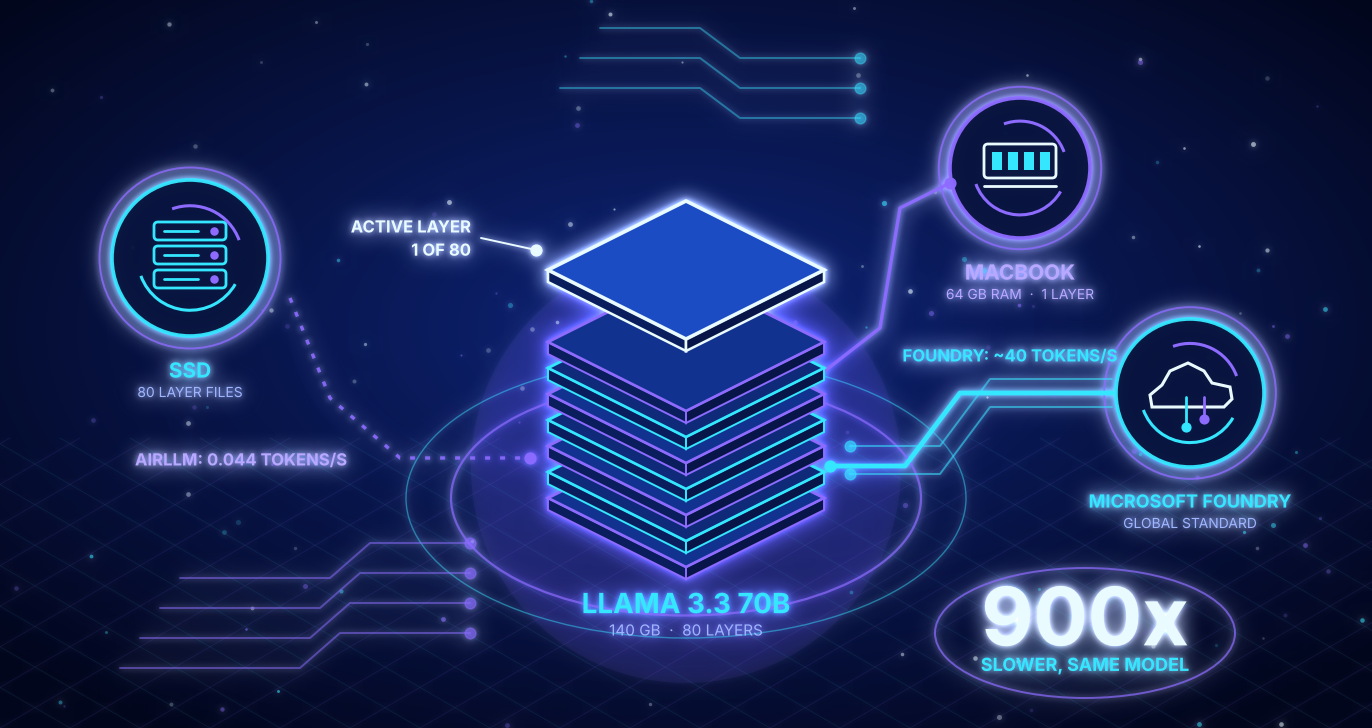
Running a 70B model on a laptop with AirLLM: what it costs in time and where Microsoft Foundry fits
AirLLM lets you run a 70 billion parameter model on a 64 GB MacBook by loading one layer at a time from disk. It works. It is also about 900 times slower than the same model in Microsoft Foundry. An answer with 200 tokens takes more than an…
Read More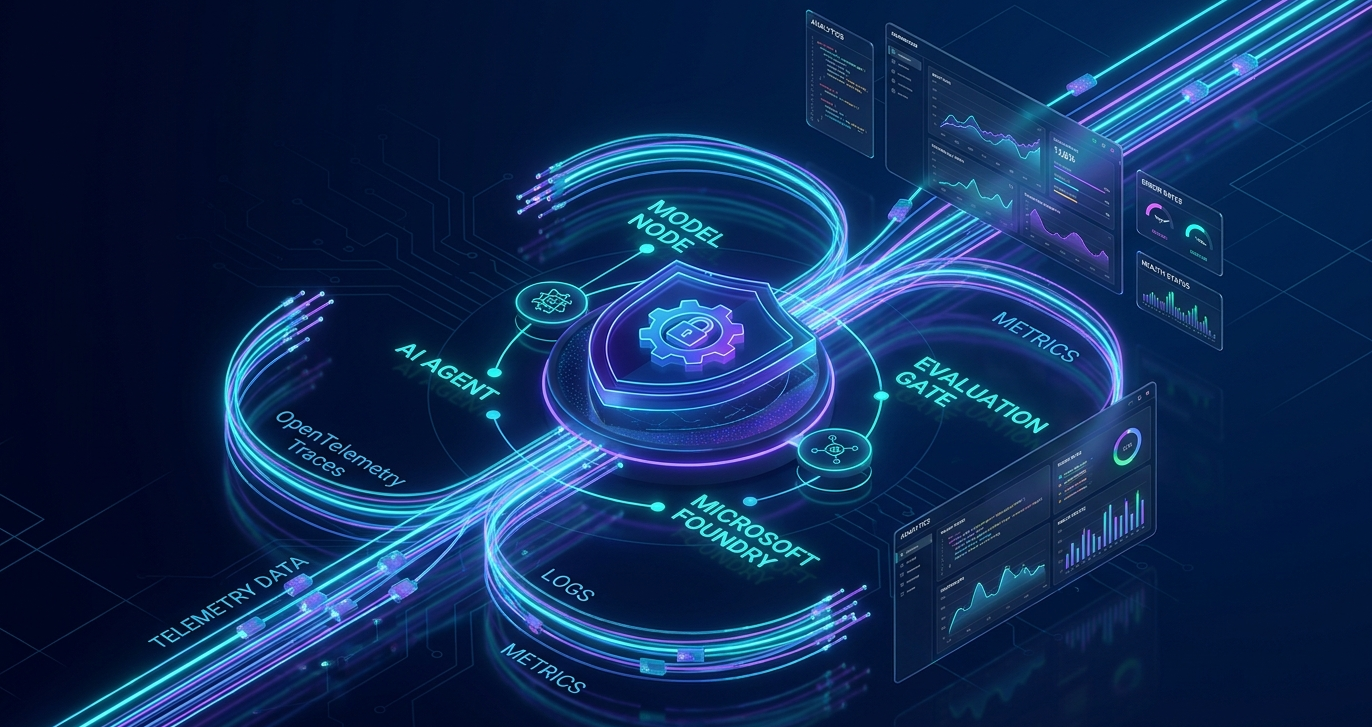
From Edge to Enterprise Cloud: Part 4 — GenAIOps, Automated Evaluations and Observability with Microsoft Foundry
In our previous posts, From Edge to Enterprise-Cloud: Part 1: Building a Cost-Free Local Loop with Foundry Local, From Edge to Enterprise Cloud: Part 2: Tool Orchestration with the Model Context Protocol and From Edge to Enterprise Cloud:…
Read More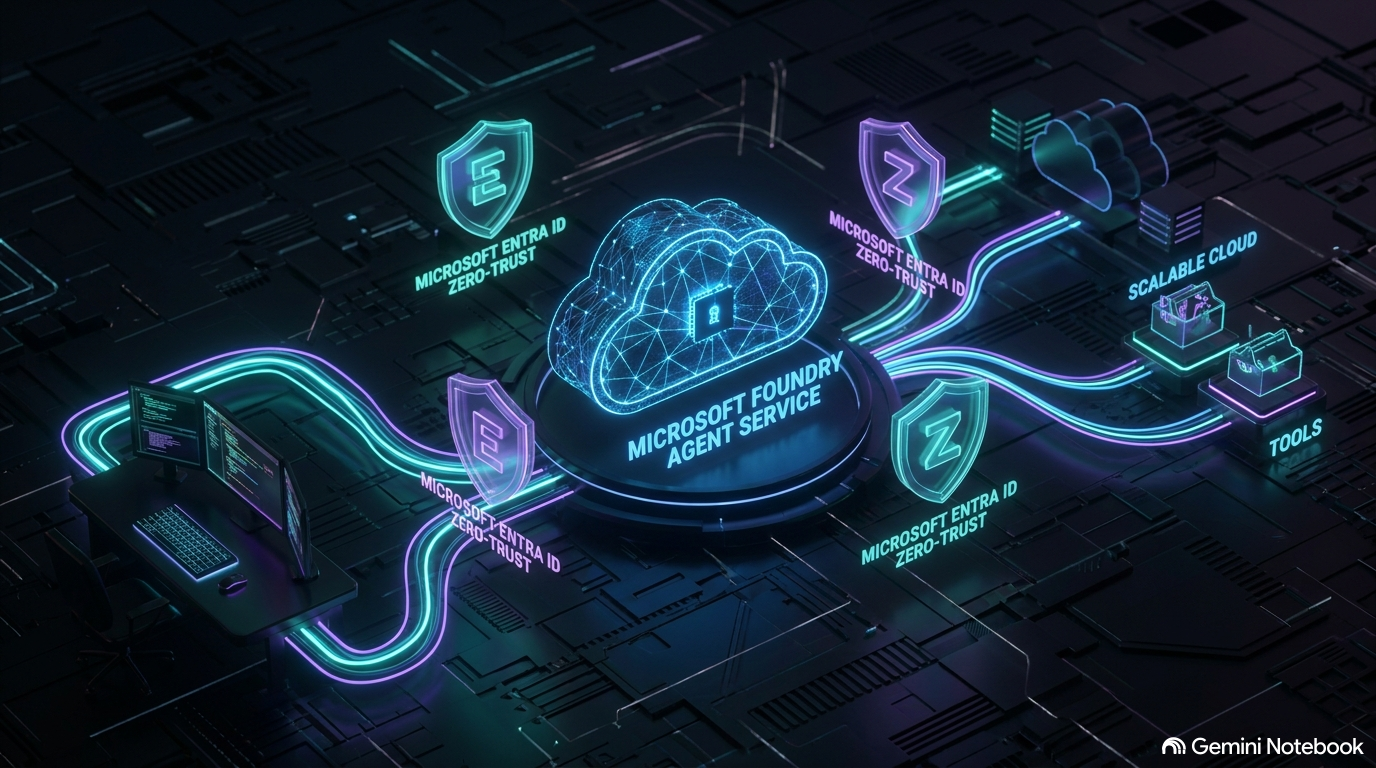
From Edge to Enterprise Cloud: Part 3 — Cloud Migration and Enterprise Identity with Microsoft Foundry Agent Service
In our previous posts, From Edge to Enterprise-Cloud: Part 1: Building a Cost-Free Local Loop with Foundry Local and From Edge to Enterprise Cloud: Part 2: Tool Orchestration with the Model Context Protocol, we established an offline,…
Read More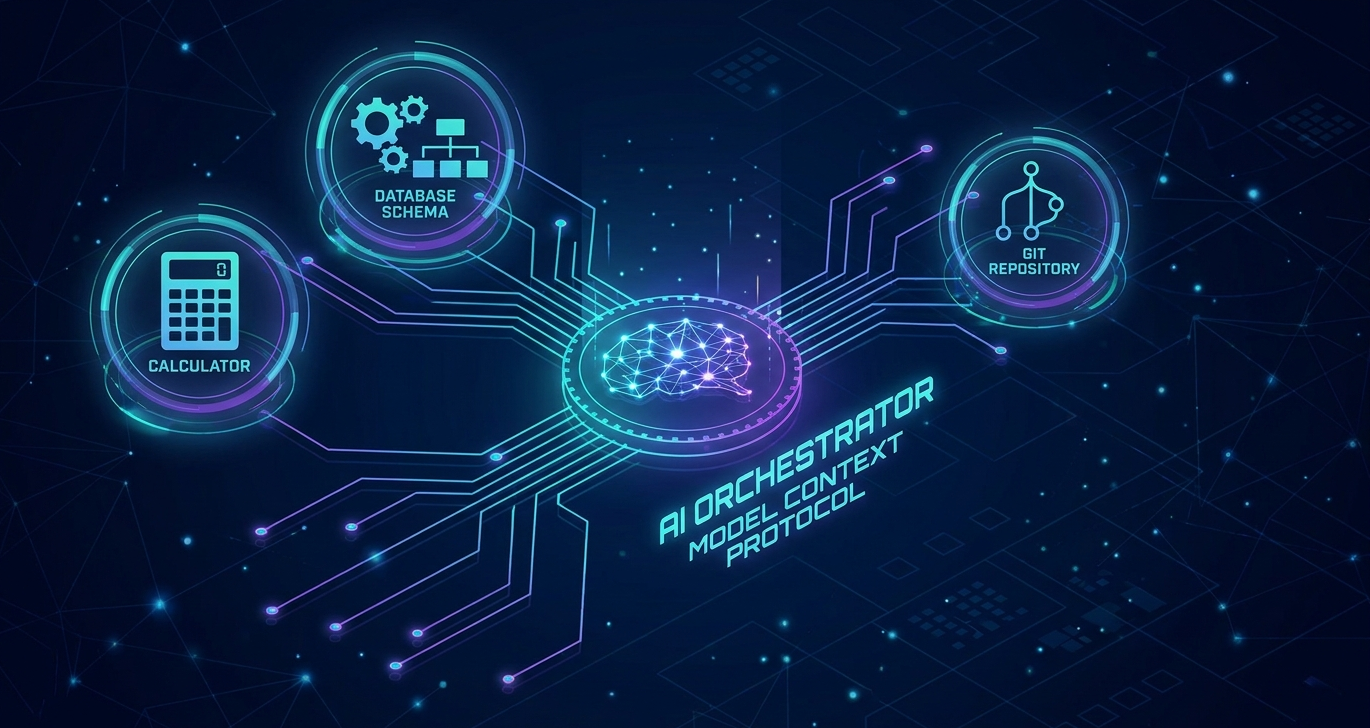
From Edge to Enterprise Cloud: Part 2 — Tool Orchestration with the Model Context Protocol
In our first installment, From Edge to Enterprise-Cloud: Part 1: Building a Cost-Free Local Loop with Foundry Local, we established a completely offline, hardware-accelerated local loop using Microsoft Foundry Local. By embedding Small…
Read More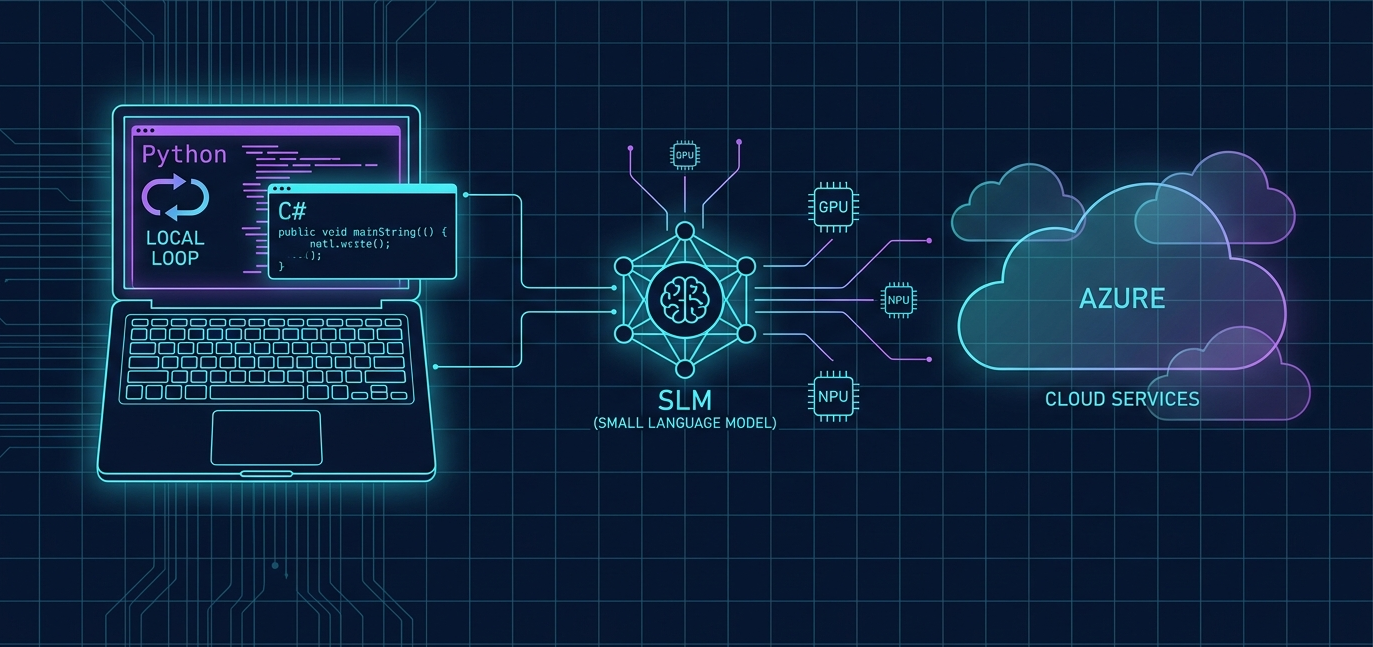
From Edge to Enterprise-Cloud: Part 1 — Building a Cost-Free Local Loop with Foundry Local
In the fast-evolving landscape of Generative AI, developers are facing a silent productivity killer: feedback loop latency and unbudgeted cloud API costs. When building AI-driven agents, every tweak to a prompt, every revision of a system…
Read More
Exploring Microsoft Foundry Local
With the Public Preview of Microsoft Foundry Local, Microsoft is taking a serious step toward bringing production-grade AI inference onto local hardware. After spending several days working with the preview, it became clear that Foundry…
Read More